Christopher LaiI am a first-year Master's student in Robotics at the University of Pennsylvania, currently working with Professor Rahul Mangharam in xLab (Safe Autonomous Systems Lab). Previously, I received my B.S. in Computer Engineering from UC Santa Barbara, where I conducted research in computer vision and multimodal learning in the Computer Vision Research Lab led by Yuan-Fang Wang, and the Four Eyes Lab under Tobias Höllerer. I'm always happy to connect about computer vision, robotics, and interesting engineering opportunities. Email / GitHub / Google Scholar / LinkedIn |
|
Technical InterestsI'm interested in computer vision, multimodal perception, and learning-based autonomy, building systems that understand dynamic environments and support reliable decisions. My interests span geometric vision and scene understanding, visual tracking and motion prediction, and relational and temporal learning for multi-agent interactions. I'm also interested in the robustness, observability, and evaluation of perception systems, particularly as they connect to decision-making in robotics and autonomous driving. |
Projects |
|
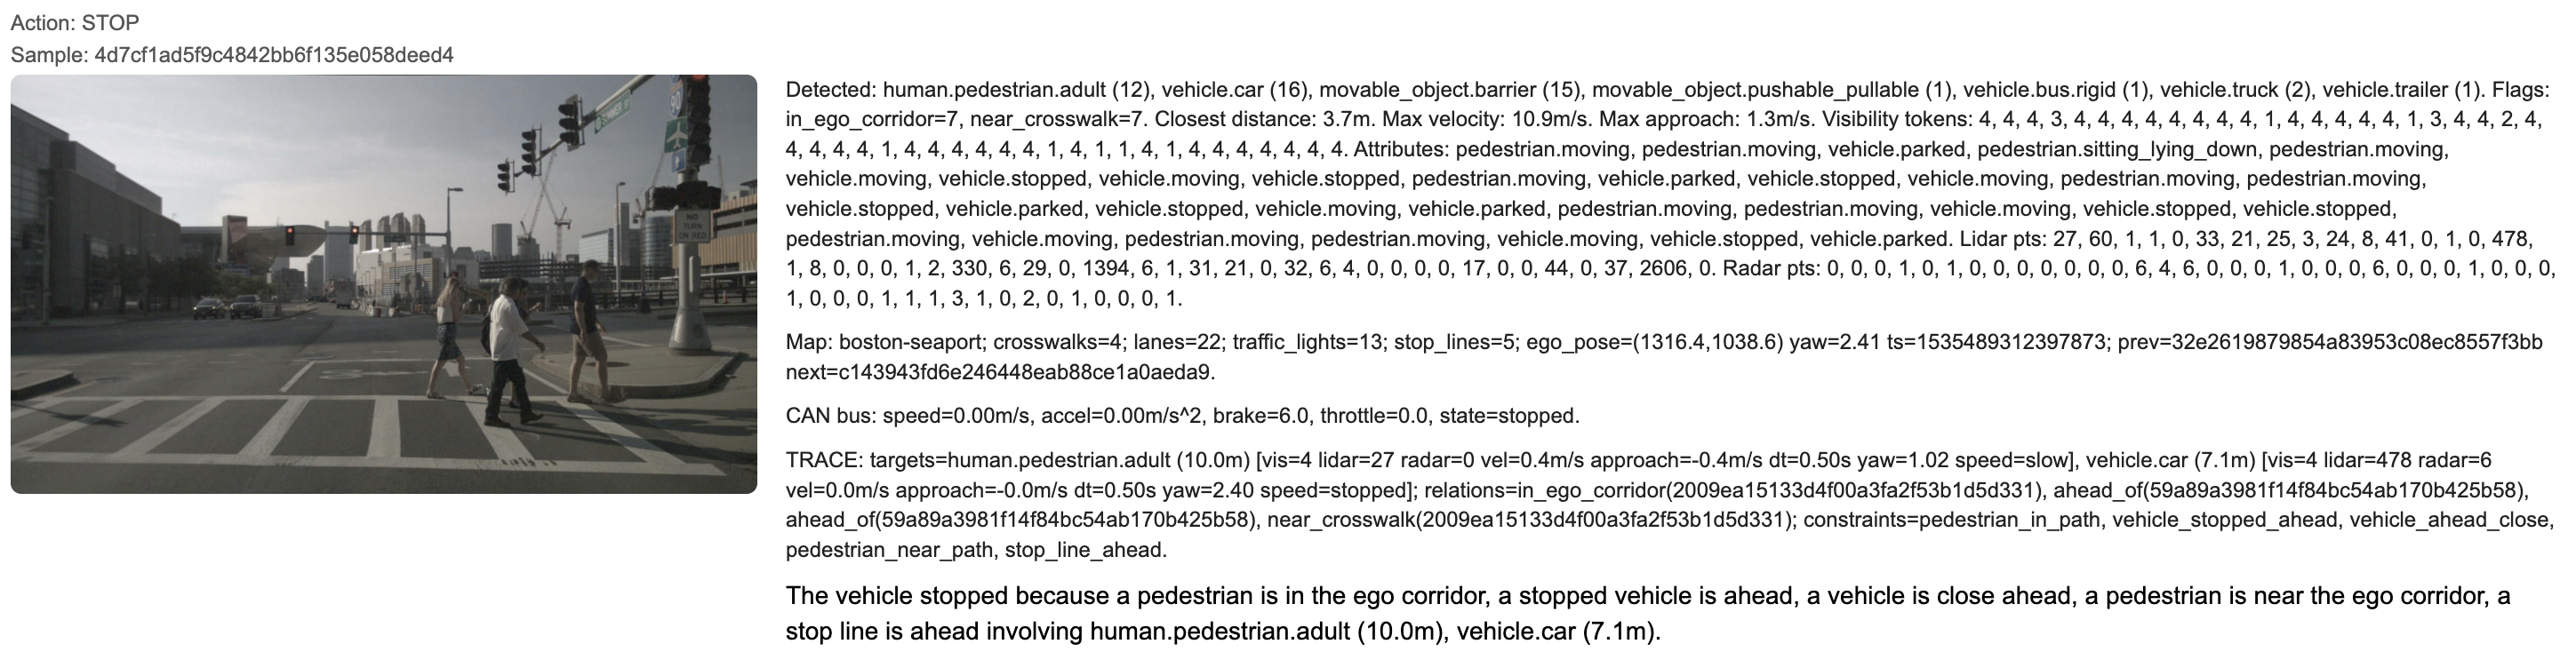
AV Perception TRACE
Autonomous Driving · Perception & Evaluation
Built an interpretable perception-to-decision pipeline on nuScenes using structured reasoning traces, learned factor models, and Understand-Decide-Verify (UDV) evaluation to analyze autonomous decision-making and failure modes. |
|
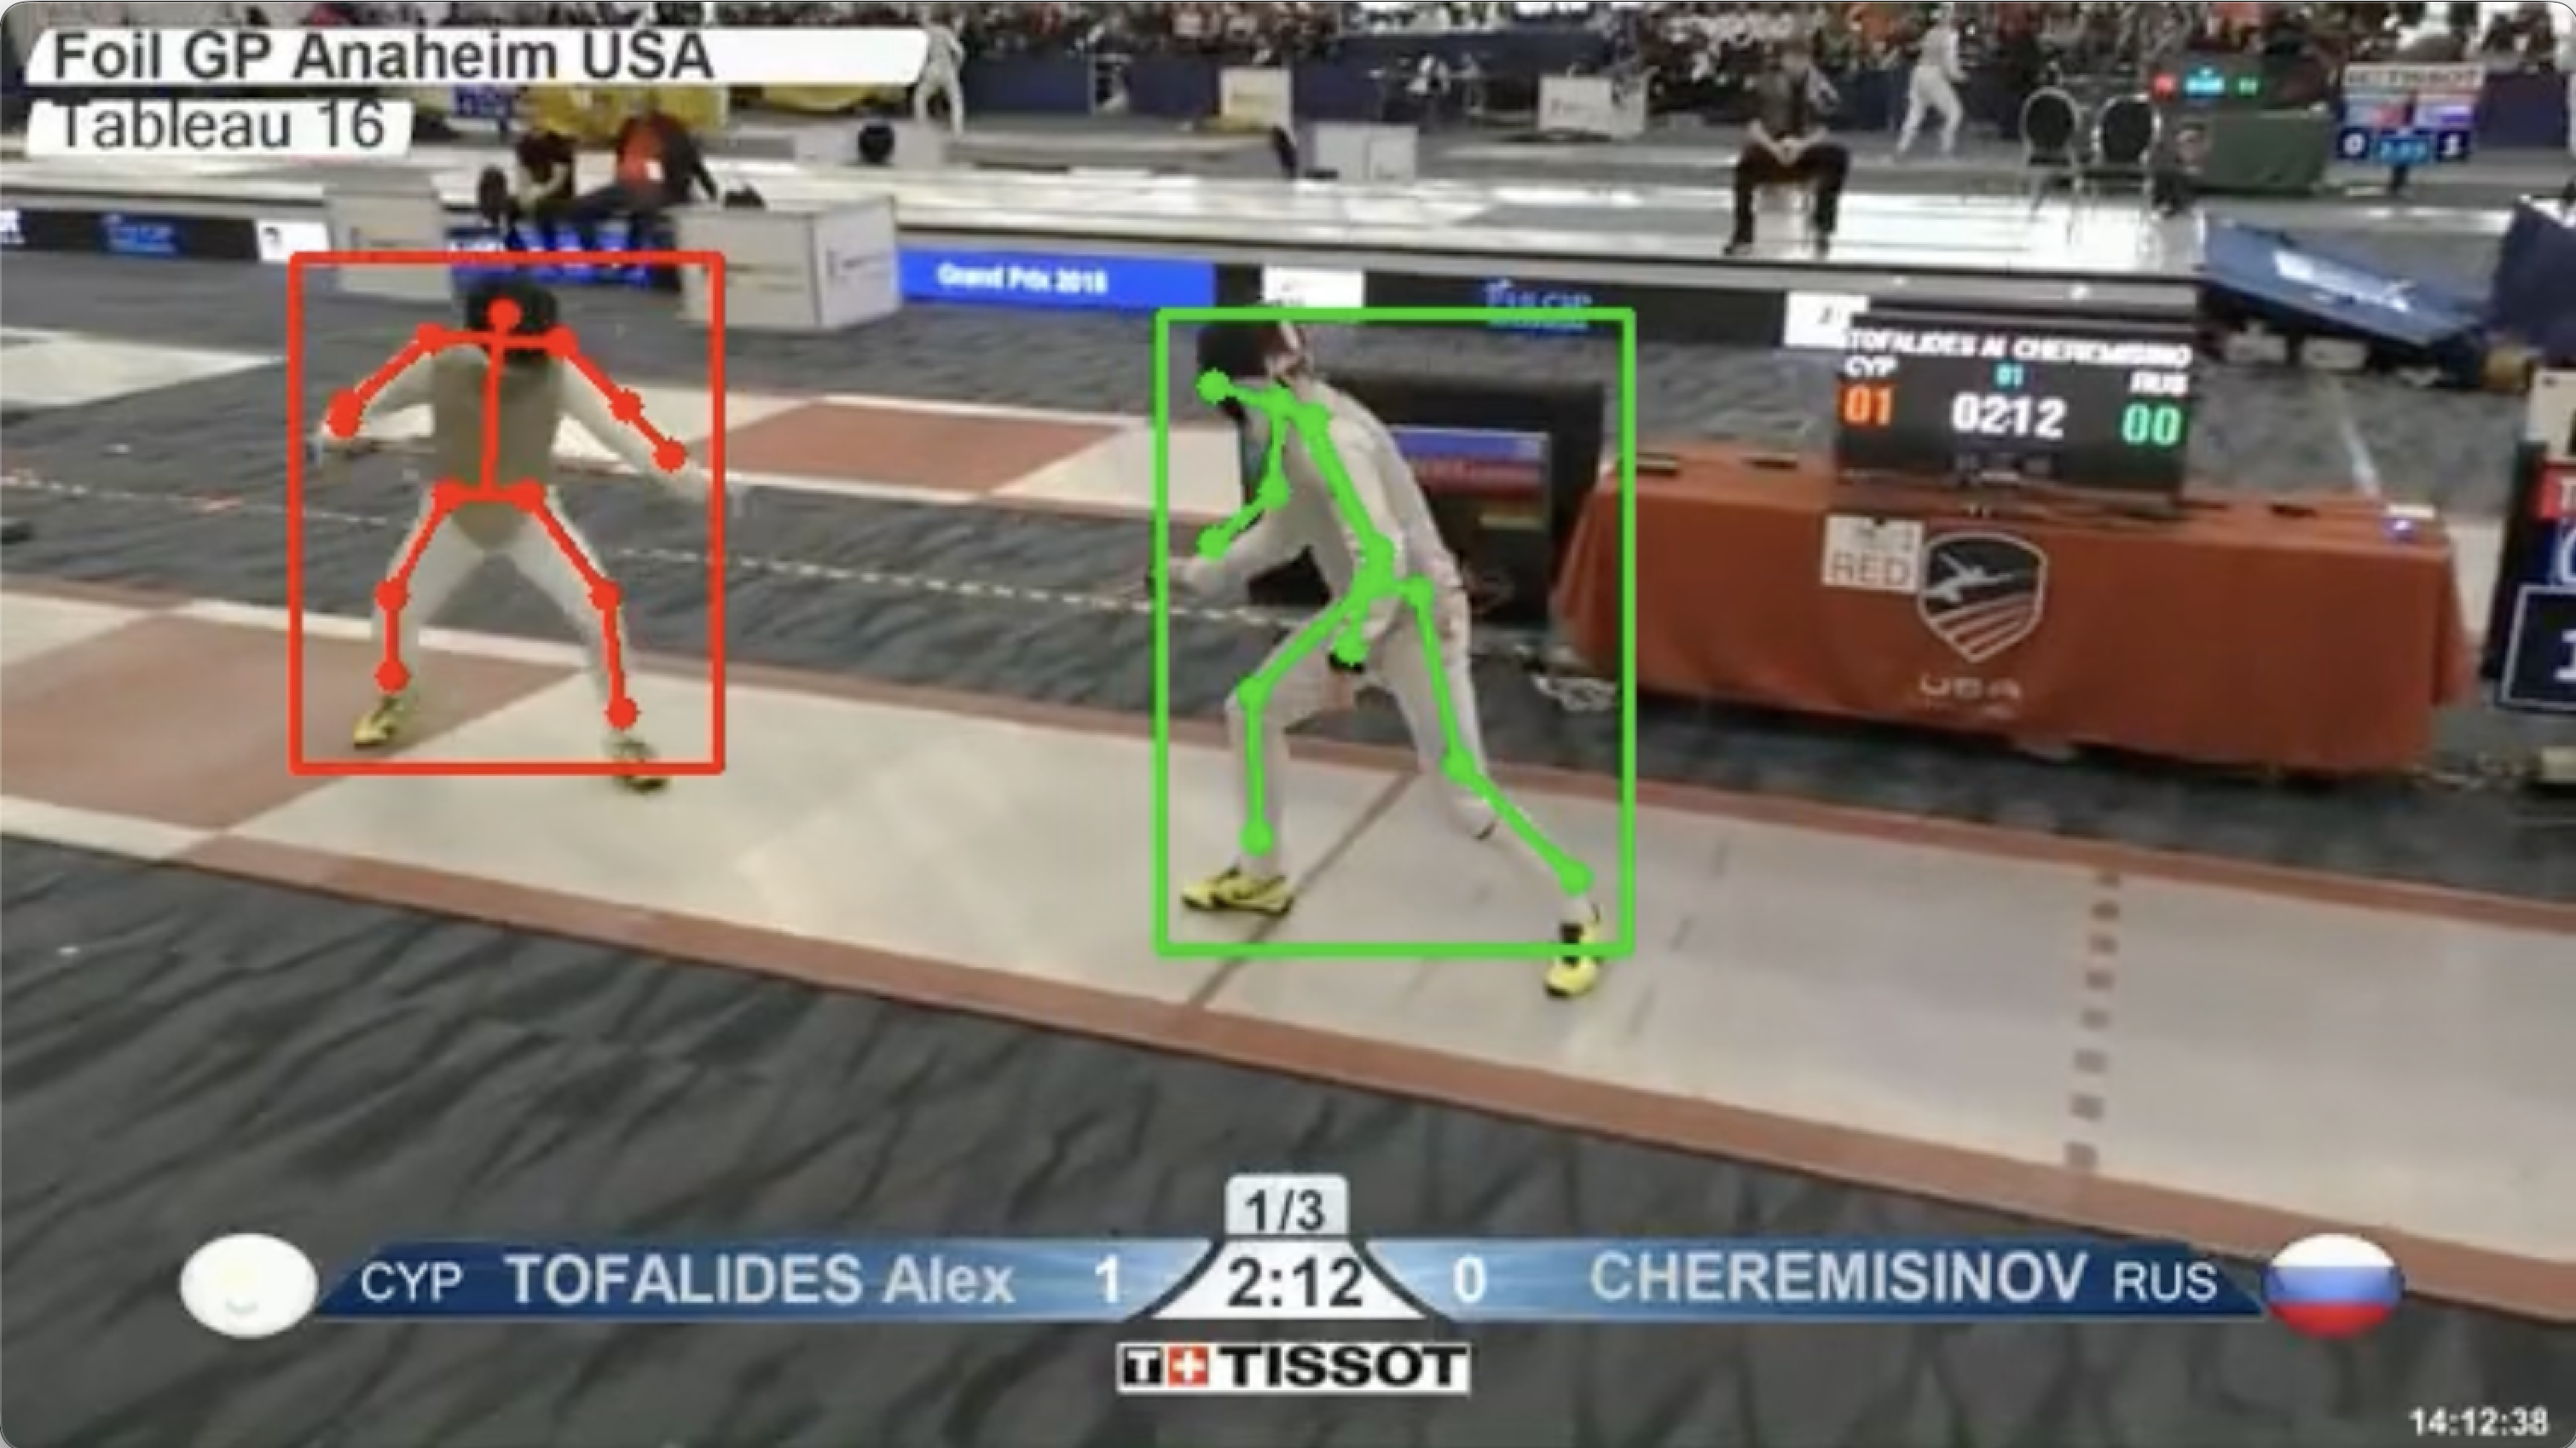
Allez Go — Multimodal Fencing Analysis
Sports Analytics · Multimodal Action Recognition
Explored fine-grained fencing action recognition using skeletal pose and audio features, combining multimodal representations to better understand athlete movements and interactions. |
Research |
|
DeepSport: A Multimodal Large Language Model for Comprehensive Sports Video Reasoning via Agentic Reinforcement LearningJunbo Zou, Haotian Xia, Zhen Ye, Shengjie Zhang, Christopher Lai, Vicente Ordonez, Weining Shen, Hanjie Chen Preprint arxiv We introduce DeepSport, the first end-to-end trained MLLM framework designed for multi-task, multi-sport video understanding, featuring active iterative reasoning with a specialized frame-extraction tool and achieving state-of-the-art performance on sports video reasoning tasks. |
|
SportR: A Benchmark for Multimodal Large Language Model Reasoning in SportsHaotian Xia, Haonan Ge, Junbo Zou, Hyun Woo Choi, Xuebin Zhang, Danny Suradja, Botao Rui, Ethan Tran, Wendy Jin, Zhen Ye, Xiyang Lin, Christopher Lai, Shengjie Zhang, Junwen Miao, Shichao Chen, Rhys Tracy, Vicente Ordonez, Weining Shen, Hanjie Chen ICLR 2026 (Poster) arxiv We introduce SportR, a multi-sports benchmark designed to train and evaluate MLLMs on fundamental reasoning required for sports intelligence, featuring images and videos with progressive reasoning tasks. |
|
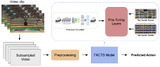
FACTS: Fine-Grained Action Classification for Tactical SportsChristopher Lai, Jason Mo, Haotian Xia, Yuan-fang Wang Preprint arxiv We introduce FACTS, a novel transformer-based approach for fine-grained action recognition in fast-paced, close-combat sports that processes raw video data directly, achieving state-of-the-art performance on fencing and boxing actions. |
|
SPORTU: A Comprehensive Sports Understanding Benchmark for Multimodal Large Language ModelsHaotian Xia, Zhengbang Yang, Junbo Zou, Rhys Tracy, Yuqing Wang, Chi Lu, Christopher Lai, Yanjun He, Xun Shao, Zhuoqing Xie, Yuan-fang Wang, Weining Shen, Hanjie Chen ICLR 2025 (Poster) arxiv We introduce SPORTU, a comprehensive benchmark designed to assess Multimodal Large Language Models (MLLMs) across multi-level sports reasoning tasks, featuring both text-based rule comprehension and video-based action recognition components. |
Industry Experience
|
|
Website design adapted from Leonid Keselman's Jekyll fork of Jon Barron's website. Last updated October 2026 |